History / From the archive001
Recovered ELIZA source code and the restoration project's own account show why a scripted reply can feel understood without any comprehension.
Event: 1 January 1966
History / From the archive002
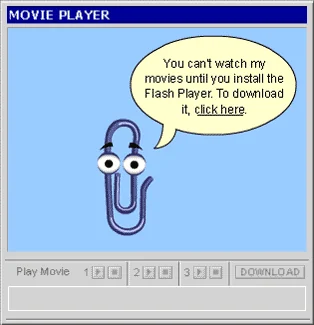
A self-mocking 2001 campaign shows how Microsoft itself described the failure of its default, on-screen Office Assistant.
Event: 31 May 2001
History / Start-here guide003
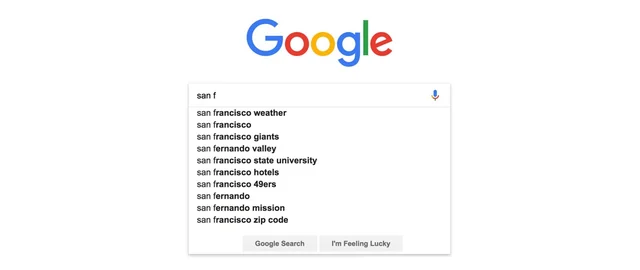
Google's current documentation states how autocomplete predictions are generated and moderated, and what they are not meant to be.
Start-here guide
History / From the archive004
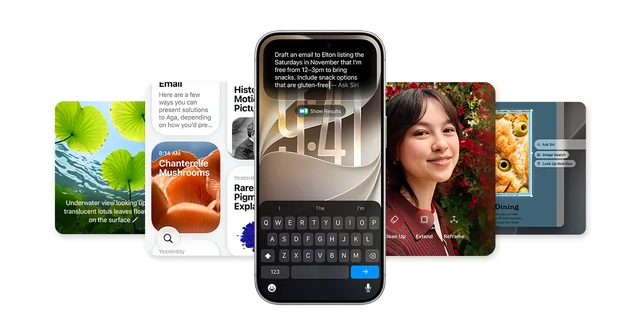
The 2011 iPhone 4S announcement named Siri's capabilities and its beta status the same day, a pattern worth checking in any assistant today.
Event: 4 October 2011
History / From the archive005
OpenAI's 2020 paper and API post explain the few-shot mechanism behind the advice to put examples inside a prompt.
Event: 28 May 2020
History / From the archive006
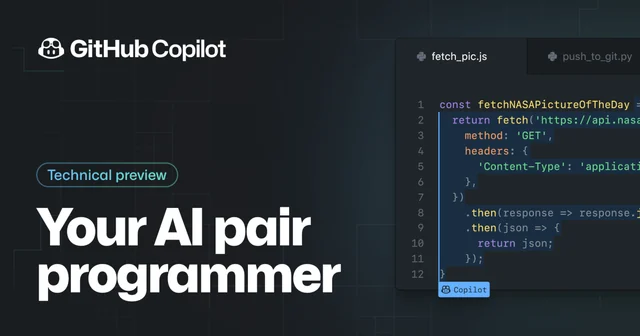
GitHub's 2021 and 2022 posts show why programmers, who can run and check code instantly, adopted generation first.
Event: 29 June 2021
History / From the archive007
OpenAI's launch post shows the model behind ChatGPT predated the product and states its own reliability limitations.
Event: 30 November 2022
History / From the archive008
Microsoft's own first-week post names long conversations, not a single bad reply, as the cause of erratic Bing chat behavior.
Event: 7 February 2023
History / From the archive009
OpenAI's GPT-4 materials pair a bar-exam score with an explicit warning about hallucination and overreliance.
Event: 14 March 2023
History / From the archive010
ai.meta.com24 February 2023
Meta's 2023 releases and license show what running a model locally changes about cost and privacy, and the rules that still apply.
Event: 24 February 2023
Start here / Start-here guide011
Vendor documentation defines the token as the unit models read, price and limit, and a token is not a word.
Start-here guide
Start here / Start-here guide012
Vendor documentation calls the context window a model's working memory, and describes what happens as a chat fills it.
Start-here guide
Prompting & checks / Start-here guide013
platform.claude.comundated document
API documentation describes temperature and sampling settings as controlled randomness, not a bug in the model.
Start-here guide
Start here / From the archive014
A September 2025 research paper and vendor help pages define hallucination and explain why guessing is often rewarded.
Event: 5 September 2025
Prompting & checks / Start-here guide015
Vendor documentation and published system-prompt text show whose instructions shape a chat before a user types.
Start-here guide
Start here / Start-here guide016
Vendor documentation explains retrieval as grounding answers in a document's own text, with stated limits.
Start-here guide
Prompting & checks / Start-here guide017
Help pages describe when assistants search the live web and warn that citations can be wrong or outdated.
Start-here guide
Privacy & safety / From the archive018
A February 2024 rollout and later expansions show what memory keeps and how a user can see or clear it.
Event: 13 February 2024
Start here / From the archive019
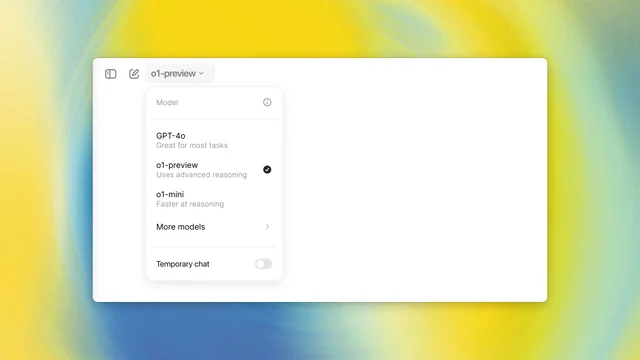
OpenAI's September 2024 o1 launch and current vendor docs show what extra thinking time buys and costs.
Event: 12 September 2024
Tools & documentation / Start-here guide020
Vendor deprecation pages set retirement dates for models and show what breaks when one arrives.
Start-here guide
Prompting & checks / Start-here guide021
The guide's current order puts message roles and structure ahead of phrasing tricks, and treats reasoning models differently.
Start-here guide
Prompting & checks / Start-here guide022
The vendor's current reference lists clarity, context and examples before role-play, and names which advice is model-specific.
Start-here guide
Prompting & checks / Start-here guide023
The API guide's role-constraints-context-task template differs from Workspace's persona-task-context-format sentence.
Start-here guide
Evidence / From the archive024
arxiv.org28 January 2022
The 2022 paper tested three large models on math and reasoning tasks and tied the gain to model scale, not wording alone.
Event: 28 January 2022
Prompting & checks / Start-here guide025
The 2020 GPT-3 paper named this in-context learning, and current vendor guides warn that too-similar examples can backfire.
Start-here guide
Evidence / From the archive026
The 2023 paper found a U-shaped accuracy curve by position, a limit worth checking before trusting a long prompt.
Event: 6 July 2023
Evidence / From the archive027
arxiv.org17 October 2023
Two studies found prompt formatting and phrasing shifted accuracy sharply and inconsistently across models.
Event: 17 October 2023
Prompting & checks / Start-here guide028
platform.claude.comundated document
A 2023 study of 162 personas found no general accuracy gain, while a vendor guide frames roles as a tone setting.
Start-here guide
Prompting & checks / Start-here guide029
OpenAI's help page names the failure as hallucinating, and a 2023 case study found every requested citation fabricated.
Start-here guide
Tools & documentation / Start-here guide030
Comparing three vendors' current libraries shows a template is a starting structure to adapt, not a finished answer to copy.
Start-here guide
Start here / Start-here guide031
help.openai.comundated document
Vendor file-upload pages describe what a pasted document becomes, and the checks that catch a draft's invented detail.
Start-here guide
Start here / Start-here guide032
arxiv.org2 May 2020
Two 2023 evaluations rate AI summaries highly overall, but neither measured whether every number and qualifier survived.
Start-here guide
Start here / Start-here guide033
A 2023 GPT evaluation and Google's own 2024 language expansion both show translation quality is uneven, not uniformly good.
Start-here guide
Work & learning / Start-here guide034
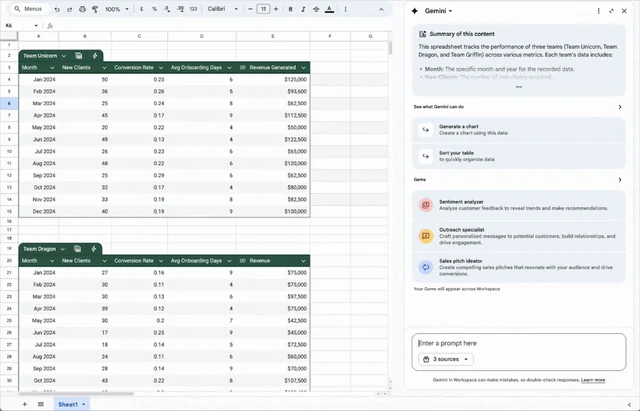
Vendor documentation says to review generated code and formulas before relying on them, and describes each tool's sandbox.
Start-here guide
Work & learning / Start-here guide035
arxiv.org20 August 2021
A 2021 study found vulnerabilities in about 40% of Copilot's suggestions, and GitHub's own survey reports faster task completion.
Start-here guide
Start here / From the archive036
OpenAI's GPT-4V system card documents hallucinations testers found, and Anthropic lists where its own vision tool is approximate.
Event: 25 September 2023
Start here / From the archive037
OpenAI's 2023 launch, its current voice FAQ, and the GPT-4o system card each describe a different layer of what voice changes.
Event: 25 September 2023
Start here / Start-here guide038
A travel-planning benchmark found GPT-4 solved 0.6% of realistic requests, and OpenAI describes how its search and links work.
Start-here guide
Privacy & safety / Start-here guide039
openai.comundated document
Usage policies classify medical guidance as high-risk, and a JAMA study of one forum found preference without testing accuracy.
Start-here guide
Privacy & safety / From the archive040
A federal judge's 2023 sanctions order documents fabricated case citations from ChatGPT, and usage policies address licensed advice.
Event: 22 June 2023
Privacy & safety / Start-here guide041
OpenAI, Anthropic and Google document different defaults and different toggles for whether a conversation trains their model.
Start-here guide
Privacy & safety / Start-here guide042
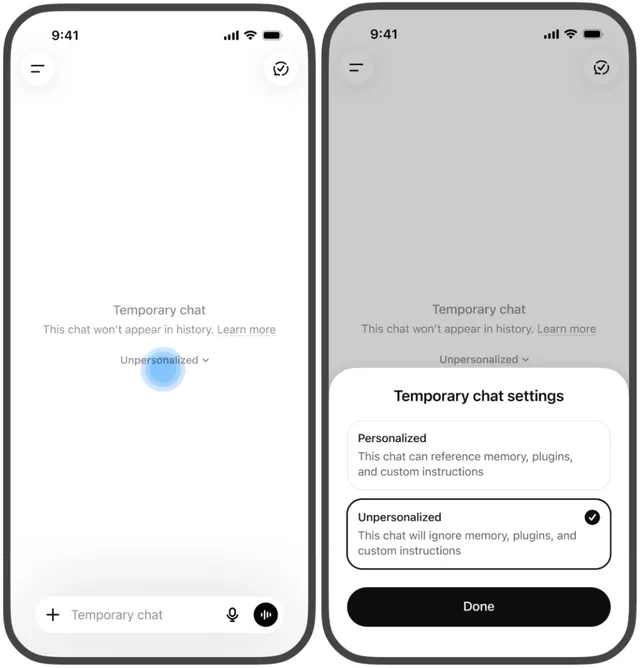
Help pages from OpenAI, Google and Anthropic each define a different reach for temporary chats, history settings and deletion.
Start-here guide
Privacy & safety / From the archive043
The Garante's March 2023 order and its April follow-up record why it paused ChatGPT and what OpenAI changed to resume service.
Event: 30 March 2023
Privacy & safety / From the archive044
OpenAI's own incident report names the redis-py bug that exposed chat titles and some billing details in March 2023.
Event: 20 March 2023
Privacy & safety / Start-here guide045
ico.org.ukundated document
ICO guidance on AI and data protection sets a lawful-basis test and a distinct meaning for accuracy that a chatbot's fluency can hide.
Start-here guide
Privacy & safety / From the archive046
edpb.europa.eu23 May 2024
The EDPB ChatGPT taskforce's 2024 report gives preliminary views on lawful basis, fairness, accuracy and data-subject rights.
Event: 23 May 2024
Privacy & safety / From the archive047
web.archive.org27 February 2023
Two 2023 FTC business-blog posts set out what an AI marketing claim must prove and what a chatbot-enabled deception still violates.
Event: 27 February 2023
Privacy & safety / Start-here guide048
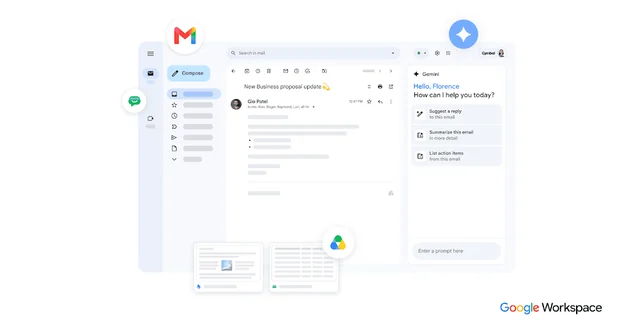
OpenAI, Anthropic and Google document contractual no-training defaults for paid business tiers that differ from consumer settings.
Start-here guide
Privacy & safety / Start-here guide049
help.openai.comundated document
Help pages and a 2025 removal show that a shared AI chat link is public by default and was briefly made searchable.
Start-here guide
Privacy & safety / From the archive050
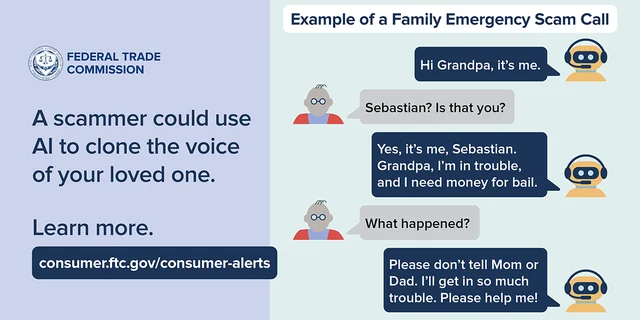
An FTC alert says short audio clips are enough to clone a voice, and recommends verifying by calling the person back on a known number.
Event: 20 March 2023
Privacy & safety / From the archive051
fcc.gov8 February 2024
An FCC ruling treats AI-generated voices in robocalls as 'artificial' under a 1991 law, opening state enforcement against voice-cloning scams.
Event: 8 February 2024
Privacy & safety / Start-here guide052
A security classification and vendor guidance describe how hidden text in a document or webpage can redirect an assistant that reads it.
Start-here guide
Privacy & safety / From the archive053
Two NCSC blog posts from August 2023 explain prompt injection and data poisoning in plain terms and what organisations can do about them.
Event: 30 August 2023
Privacy & safety / From the archive054
A joint CISA-NCSC guidance document sets secure-by-design practices for building AI systems, agreed globally for the first time, the agencies state.
Event: 27 November 2023
Privacy & safety / Start-here guide055
Content Credentials and SynthID document how an image was made, but the standards say that absence of a credential proves nothing.
Start-here guide
Privacy & safety / Start-here guide056
OpenAI, Anthropic and Google state different minimum ages and parental-control approaches in their current terms and help pages.
Start-here guide
Privacy & safety / Start-here guide057
Google recommends 2-Step Verification for any account; Claude's own help pages describe logging in without a password at all.
Start-here guide
Privacy & safety / Start-here guide058
support.claude.comundated document
Anthropic's and Google's help pages describe separate paths for flagging harmful output and for reviewing account or policy decisions.
Start-here guide
Evidence / From the archive059
A pre-registered study of 758 BCG consultants found large gains on tasks inside AI's frontier and worse accuracy on one task outside it.
Event: 22 September 2023
Evidence / From the archive060
nber.org1 April 2023
An NBER study of 5,179 support agents found a generative AI assistant raised productivity most for less experienced workers.
Event: 1 April 2023
Evidence / From the archive061
economics.mit.edu2 March 2023
A randomized experiment on 444 professionals found ChatGPT cut writing time and raised quality most for weaker writers.
Event: 13 July 2023
Evidence / From the archive062
arxiv.org13 February 2023
A randomized controlled trial of 95 freelance programmers found GitHub Copilot cut time to build one HTTP server by 55.8%.
Event: 13 February 2023
Evidence / From the archive063
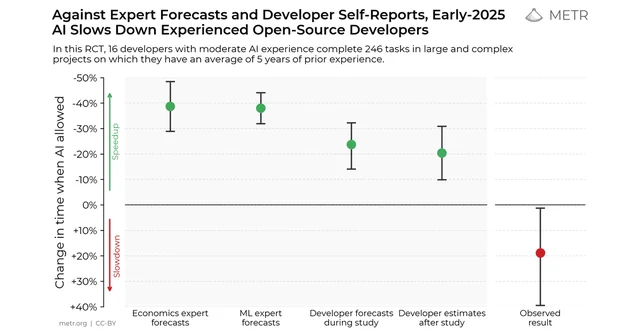
METR timed 16 experienced open-source developers and found AI tools increased task time by 19% even as developers believed they were faster.
Event: 10 July 2025
Evidence / From the archive064
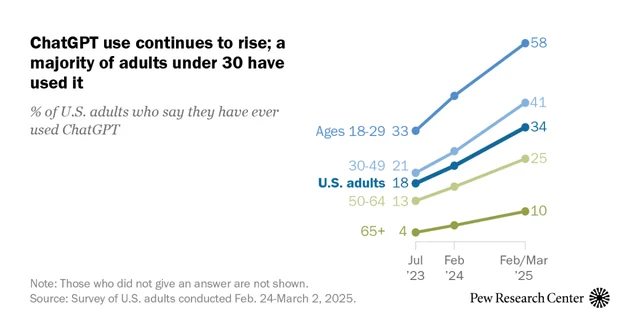
Pew's American Trends Panel surveys found 34% of US adults had used ChatGPT by 2025, about double the 2023 share, with use split by age and purpose.
Event: 25 June 2025
Evidence / From the archive065
The Anthropic Economic Index analysed about a million Claude.ai conversations by occupational task, and Anthropic names its own method's blind spots.
Event: 10 February 2025
Evidence / From the archive066
openai.com15 September 2025
An OpenAI and Harvard analysis of 1.5 million ChatGPT messages found about 70% of consumer use is non-work, mostly practical guidance.
Event: 15 September 2025
Evidence / Start-here guide067
dl.acm.org19 April 2023
Two controlled experiments found people over-rely on confident AI explanations and misjudge when to trust their own answer instead.
Start-here guide
Evidence / Start-here guide068
Pew and a UK government tracker found most people cannot reliably identify AI in everyday products or say how their data is used.
Start-here guide
Tools & documentation / Start-here guide069
Vendors' own pricing pages, read on the retrieval date, show what a subscription actually adds beyond a higher message limit.
Start-here guide
Tools & documentation / Start-here guide070
Microsoft and Google's own documentation shows what a workplace assistant can read from an account and which setting controls it.
Start-here guide
Tools & documentation / From the archive071
OpenAI's GPTs and Projects and Anthropic's Projects save instructions and files for reuse, but keep each one's memory separate.
Event: 6 November 2023
Tools & documentation / Start-here guide072
Ollama, LM Studio and llama.cpp's own documentation states the hardware a local model needs and what running it locally buys.
Start-here guide
Tools & documentation / From the archive073
Google's own announcement and help page describe how AI Overviews are generated and state plainly that they can be wrong.
Event: 14 May 2024
Tools & documentation / Start-here guide074
Perplexity's own documentation describes how it attaches numbered citations and states plainly that its answers can be wrong.
Start-here guide
Tools & documentation / From the archive075
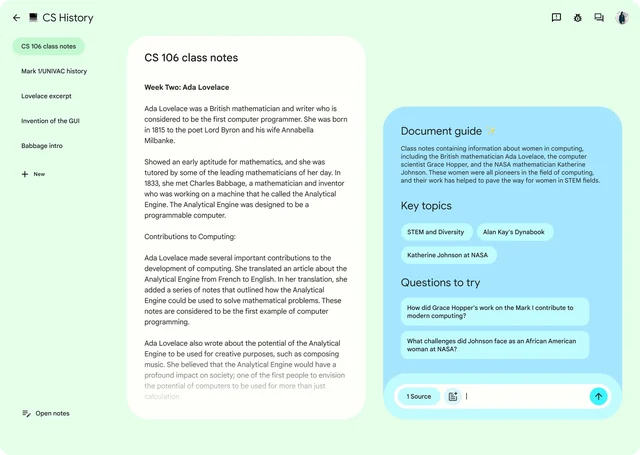
Google's NotebookLM launch post and current help pages describe a tool restricted to a user's own uploaded sources.
Event: 12 July 2023
Tools & documentation / Start-here guide076
Microsoft Edge and Chrome document what their built-in AI sidebars can see across open tabs and how to limit it.
Start-here guide
Tools & documentation / Start-here guide077
Developer pricing pages price the same models per million tokens, a different unit from a subscription's flat monthly fee.
Start-here guide
Tools & documentation / Start-here guide078
Vendor status pages, read on the retrieval date, show recent incidents and make the case for a fallback plan.
Start-here guide
Work & learning / Start-here guide079
NPR, Harvard and the UK government each publish a written AI-use policy, and comparing them shows what a policy actually has to cover.
Start-here guide
Work & learning / From the archive080
The UK's January 2024 generative AI framework set ten principles for civil servants and was withdrawn thirteen months later.
Event: 18 January 2024
Work & learning / From the archive081
whitehouse.gov28 March 2024
OMB's March 2024 memo set minimum practices and a public opt-out for risky federal AI, before a 2025 memo rescinded and replaced it.
Event: 28 March 2024
Work & learning / Start-here guide082
nature.comundated document
Nature, ICMJE and Amazon KDP each set their own disclosure line for AI-assisted writing, and the lines do not match.
Start-here guide
Work & learning / Start-here guide083

JCQ and Oxford both treat undeclared AI-generated work as misconduct, with the default set to not permitted.
Start-here guide
Work & learning / From the archive084
OpenAI withdrew its text classifier for low accuracy, and a Stanford study found detectors penalise non-native English writers most.
Event: 20 July 2023
Work & learning / Start-here guide085
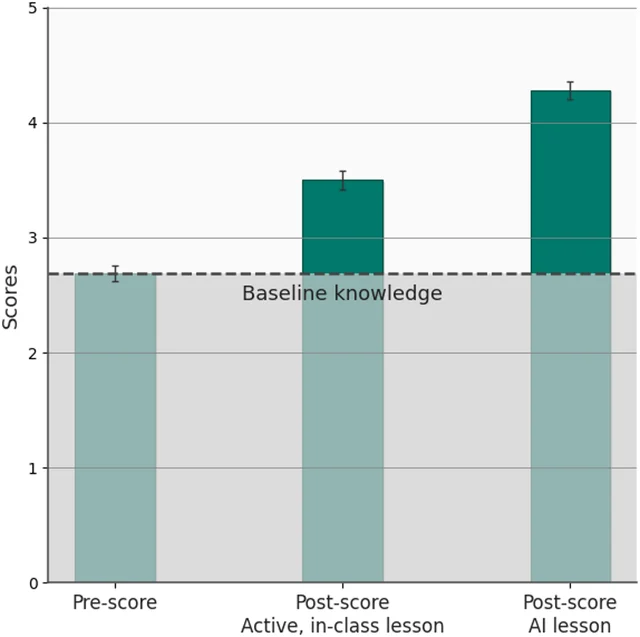
Two 2025 randomised trials found generative AI can help or hurt learning depending on whether it is built to tutor.
Start-here guide
Work & learning / Start-here guide086
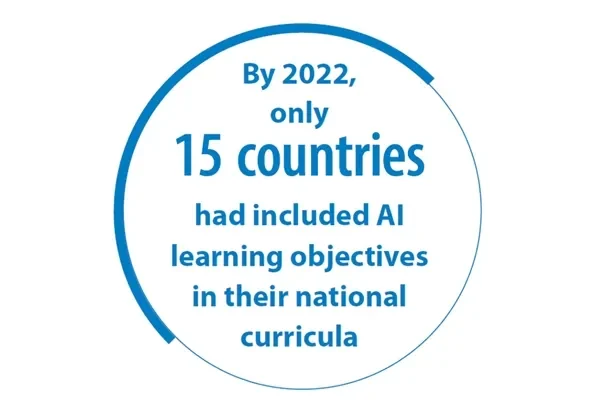
UNESCO's competency framework and the EU AI Act's Article 4 both set out what understanding AI is supposed to look like.
Start-here guide
Work & learning / From the archive087
eur-lex.europa.eu12 July 2024
Article 50 of the EU AI Act, in force from August 2026, requires disclosure that content or a conversation came from AI.
Event: 12 July 2024
Work & learning / Start-here guide088
openai.comundated document
OpenAI and Anthropic assign their rights in AI output to the user, but the US Copyright Office says a prompt alone is not authorship.
Start-here guide
Prompting & checks / Start-here guide089
A routine built from vendor guidance and a fact-checking study for testing an assistant's answer before acting on it.
Start-here guide
Start here / Start-here guide090
Grounded, reasoning and local assistants are built for different jobs, as their own documentation describes.
Start-here guide
Privacy & safety / Start-here guide091
Regulator guidance and vendor data pages describe why other people's data and secrets need a reason before pasting.
Start-here guide
Prompting & checks / Start-here guide092
platform.claude.comundated document
Three vendors' own prompting guides describe the same shape: goal, input, constraints, format and a check.
Start-here guide
Privacy & safety / Start-here guide093
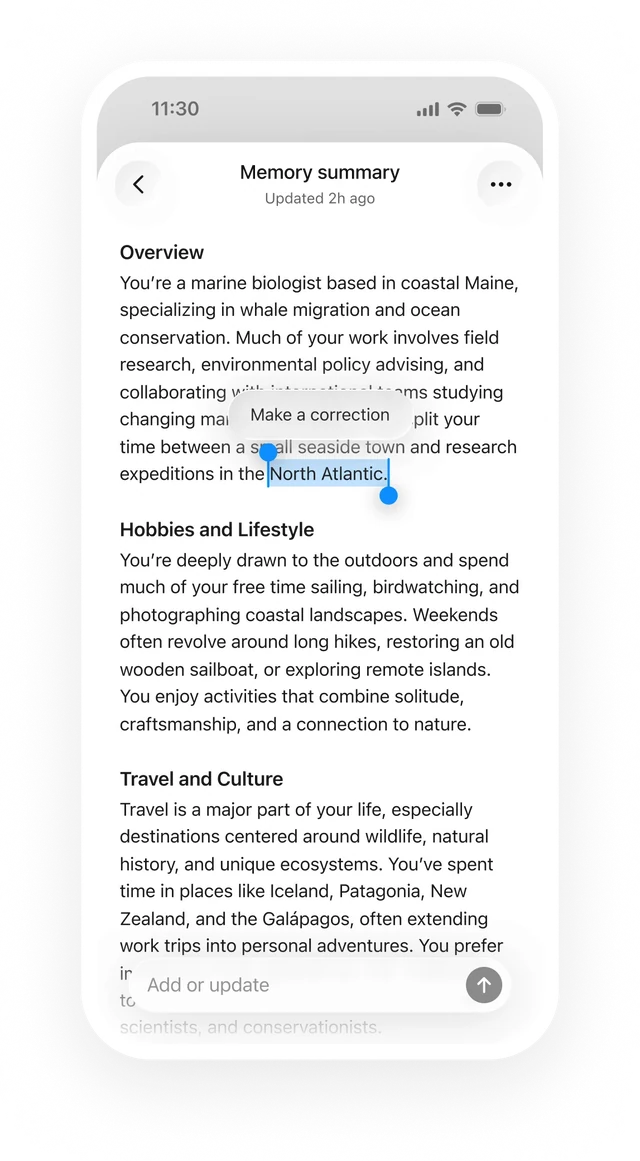
Memory, activity history and model-training controls, as three vendors' own help pages describe them.
Start-here guide
Tools & documentation / Start-here guide094
What three vendors' own model documentation states about limits, cutoffs and safety testing, for a non-expert reader.
Start-here guide
Start here / Start-here guide095
Usage policies and an over-reliance study mark where the documentation itself says to stop relying on an assistant.
Start-here guide
Work & learning / Start-here guide096
nature.comundated document
Editorial policy, a share-link FAQ and a government playbook describe what counts as a usable record of AI use.
Start-here guide
Start here / Start-here guide097
help.openai.comundated document
A plain, checkable first explanation for a new user, built from three vendors' own explainer pages.
Start-here guide
Start here / Start-here guide098
Release notes and settings pages from three vendors show why models change and configurations do not stay put.
Start-here guide
Privacy & safety / From the archive099
The CNIL's 2024 guidance on generative AI tells organisations and staff what counts as safe to type into a consumer AI tool.
Event: 18 July 2024
Privacy & safety / From the archive100
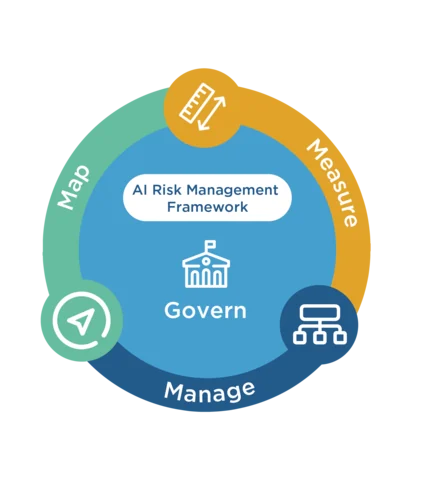
NIST's voluntary framework organizes AI risk management into four functions and was built with input from over 240 organizations, NIST states.
Event: 26 January 2023